Beyond the Caption: What Building Our Own Visual-Logic Benchmark Taught Us About Today’s VLMs
See what Innodata’s visual reasoning benchmark reveals about where today’s VLMs succeed, fail, and misread visual details.
See what Innodata’s visual reasoning benchmark reveals about where today’s VLMs succeed, fail, and misread visual details.
Explore the data robots need to learn, from egocentric video and motion capture to teleoperation, retargeting, and safety evaluation.
What Robots Eat: There’s No Such Thing as a Free Lunch When You’re Training Robots Read More »
Explore six questions for aligning agents with enterprise context, controls, systems, evaluation, and oversight.
Six Questions to Ask Before Deploying an AI Agent into an Enterprise Workflow Read More »
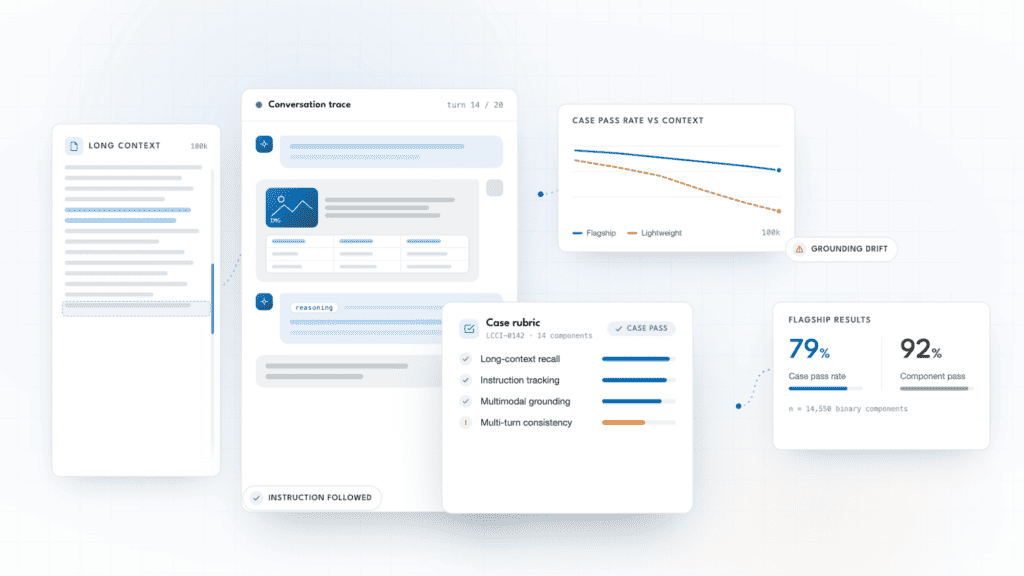
Explore Innodata’s LCCI Benchmark for long-context LLM evaluation across multi-turn conversations, multimodal inputs, and real-world model failures.
What’s in a Benchmark? Rethinking “Thinking” in Long Context Conversations Read More »
Innodata’s ICAB benchmark evaluates how well LLMs understand implicit cultural context across languages, locales, and multimodal tasks.
Cultural Alignment of LLMs Is More Than Just Trivia. It’s Applied Understanding. Read More »
Why AI systems favor average results over the best ones, and how robust reinforcement learning improves real-world performance.
The Hidden Problem with AI Optimization and Sampling Read More »