Beyond the Caption: What Building Our Own Visual-Logic Benchmark Taught Us About Today’s VLMs
See what Innodata’s visual reasoning benchmark reveals about where today’s VLMs succeed, fail, and misread visual details.
See what Innodata’s visual reasoning benchmark reveals about where today’s VLMs succeed, fail, and misread visual details.
Explore the data robots need to learn, from egocentric video and motion capture to teleoperation, retargeting, and safety evaluation.
Explore six questions for aligning agents with enterprise context, controls, systems, evaluation, and oversight.
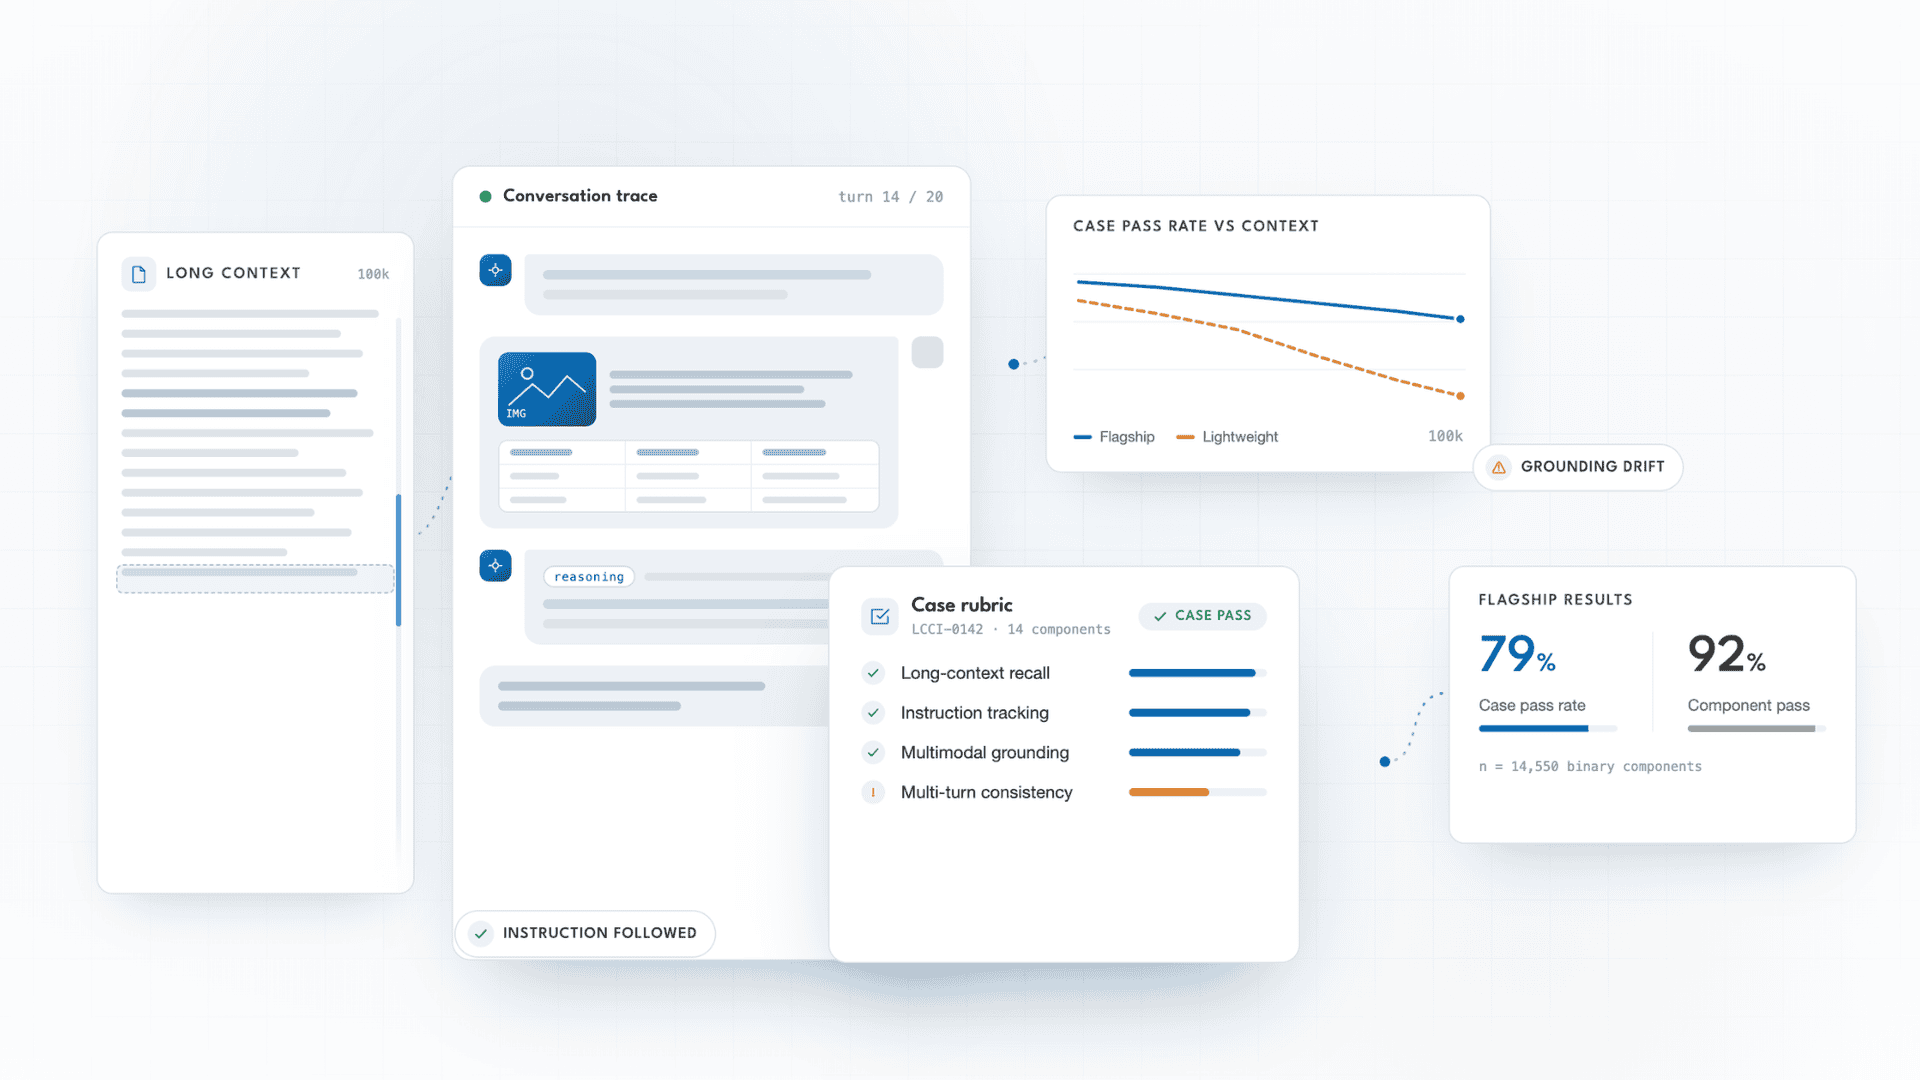
Explore Innodata’s LCCI Benchmark for long-context LLM evaluation across multi-turn conversations, multimodal inputs, and real-world model failures.
Innodata’s ICAB benchmark evaluates how well LLMs understand implicit cultural context across languages, locales, and multimodal tasks.
Why AI systems favor average results over the best ones, and how robust reinforcement learning improves real-world performance.
How kinematics-based motion analysis improves data labeling, automated quality control, and computer vision models for fitness and robotics.
Physical AI starts with data, not models. Learn how ontologies and context drive smarter, real-world AI systems.
AI systems can fail due to hidden blind spots. Learn how enterprises detect edge cases and structural gaps before deployment.